


Node.js Scraping with Cheerio & Proxies: A Code-First Guide
Build production-grade scrapers with Cheerio and axios. Covers proxy rotation as an interceptor, concurrency with p-limit, error handling for 403/429, and a full 10k-URL scraping pipeline.


Page 8 of 14
Build production-grade scrapers with Cheerio and axios. Covers proxy rotation as an interceptor, concurrency with p-limit, error handling for 403/429, and a full 10k-URL scraping pipeline.
Build undetectable Puppeteer crawlers by combining puppeteer-extra stealth plugin with residential proxy rotation. Covers fingerprint randomization, per-context proxies, and fleet scaling.
Master authenticated proxies in Selenium with selenium-wire, Firefox profiles, stealth plugins, rotating IP pools, and containerized Grid fleets — with full code samples.
Discover how sneaker monitoring tools use residential and ISP proxies to detect drops, track stock, and send price alerts — without automating checkout on sites that prohibit it.
Japanese e-commerce sites aggressively block foreign IPs and serve different catalogs to domestic users. This guide covers why JP-origin proxies are mandatory, how to handle Shift-JIS encoding and CJK text, APPI compliance, konbini payment quirks, and city-level geo-targeting for Tokyo and Osaka.
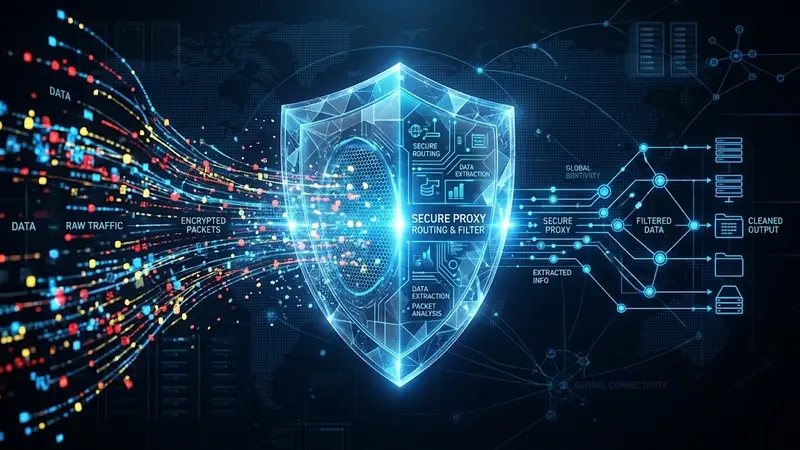
A practitioner's guide to accessing truly public Facebook data with residential proxies and browser automation — covering Meta's detection stack, legal precedents, and when to use the Graph API instead.
Build a streetwear monitoring system that catches Supreme, Kith, Palace, BAPE and ALD drops. Covers residential proxy strategy, Shopify polling architecture, and per-brand nuances—with code.
Build production-grade Scrapy proxy rotation with custom downloader middleware, retry logic, headless browser integration, and per-IP monitoring. Full code examples included.
Reddit's 2023 API pricing changes made official access expensive. This guide covers scraping public Reddit data with proxies — from proxy selection to rate-limit handling, with runnable Python and Node.js examples.
A technical deep-dive into DataDome's detection stack — TLS fingerprinting, browser fingerprinting, behavioral signals, IP reputation — and how to configure residential proxies and stealth browsers for legitimate, clean automation.
A pragmatic guide to scraping eBay—when to use the Finding/Browse APIs vs HTML, which proxy type actually works, and production-ready Python code for parsing .s-item grids, auction data, and seller analytics.
A code-first guide to configuring HTTP proxies in Rust with reqwest, hyper, tokio concurrency, rotating proxy pools, TLS options, and production-ready error handling.